6. Gathering và dựng cây hierarchy theo version#
6.1 Thiết kế compilation path và phân cấp AST/Tree#
Multi-file Gathering (
gather.py): quét các tệp.textìm\documentclass/\documentstyle. Khi có nhiều ứng viên root, thuật toán đối chiếu tiêu đề từ metadata M1 (hoặc dùng--root-overrides); bỏ qua các lệnh nằm sau comment%và đi theo\input/\includebắc cầu từ thư mục biên dịch, dừng tại\endinputhoặc\end{document}để loại file.texthừa.Cây phân cấp (
hierarchy.py): nút gốc làdocument, tớichapter/section/subsection...,paragraph,list/item, và lá nhỏ nhất làsentence,block_formula,figure(gộp cảtablethànhfigure). Bộ tách câu bảo vệ nội dung trong toán$...$, lệnh TeX, URL, số thập phân (3.14) và viết tắt (e.g.,i.e.,et al.,Fig. 1). Mục References/Bibliography tách khỏi cây;AcknowledgementsvàAppendix(\section*,\appendix) được giữ lại.
6.2 Ví dụ thực thi gathering & hierarchy từ code thật#
Toàn nhóm (5 thành viên): 25,000 paper / 41,498 version | Cập nhật: 2026-11-22
Root: main.tex | Compilation path: ['main.tex', 'sections/intro.tex'] | Diagnostics: []
| node_id | parent_id | kind | content | |
|---|---|---|---|---|
| 0 | 0 | NaN | document | Demo Multi-file Paper |
| 1 | 1 | 0.0 | section | Introduction |
| 2 | 2 | 1.0 | paragraph | First sentence with Fig. 1 and value 3.14. |
| 3 | 3 | 2.0 | sentence | First sentence with Fig. 1 and value 3.14. |
| 4 | 4 | 1.0 | list | \begin{itemize}\item First point.\item Second ... |
| 5 | 5 | 4.0 | item | First point. |
| 6 | 6 | 5.0 | paragraph | First point. |
| 7 | 7 | 6.0 | sentence | First point. |
| 8 | 8 | 4.0 | item | Second point. |
| 9 | 9 | 8.0 | paragraph | Second point. |
| 10 | 10 | 9.0 | sentence | Second point. |
| 11 | 11 | 1.0 | block_formula | x + y = z |
| 12 | 12 | 1.0 | figure | \centering\begin{tabular}{cc}\toprule A & B \\... |
| 13 | 13 | 0.0 | section | Acknowledgements |
| 14 | 14 | 13.0 | paragraph | We thank the team. |
| 15 | 15 | 14.0 | sentence | We thank the team. |
| 16 | 16 | 0.0 | section | Appendix Proof |
| 17 | 17 | 16.0 | paragraph | Extra proof detail. |
| 18 | 18 | 17.0 | sentence | Extra proof detail. |
6.3 Tác động nâng cấp parser qua Pilot (v1 -> v2) và phân bố 25.000 bài#
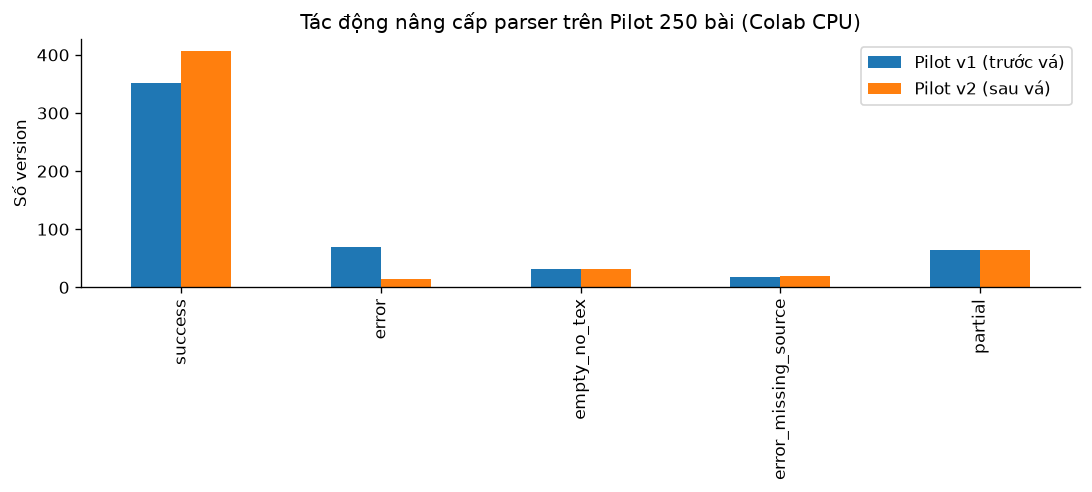
Trước khi chạy toàn bộ 25.000 bài, nhóm chạy Pilot phân tầng 250 bài (536 version) trên Colab CPU, phát hiện và vá 4 nhóm lỗi thực tế (tách nhánh \cite{{k1},{k2}}, deduplicate khóa trùng trong cùng version theo độ ưu tiên .bib > inline > .bbl, chặn crash khoảng nửa mở [0, 1) sau \item, phân giải đa root theo tiêu đề M1, mở rộng tập môi trường list như compactitem/enumerate*/inparaenum, tối ưu parse_bibtex bằng lazy field parsing cho các file .bib khổng lồ như anthology.bib 43,8 MB).
Bảng 6.1. So sánh Pilot 250 bài / 536 version trên Colab CPU trước & sau nâng cấp parser.
| Pilot v1 (trước vá) | Pilot v2 (sau vá) | |
|---|---|---|
| success | 352 | 407 |
| error | 70 | 14 |
| empty_no_tex | 32 | 32 |
| error_missing_source | 17 | 19 |
| partial | 65 | 64 |
Bảng 6.2. Phân tầng mức độ hoàn thiện trên toàn bộ 25.000 bài.
| Số bài báo | |
|---|---|
| Mọi version empty (PDF-only / no LaTeX) | 2006 |
| Parsed đủ (không lỗi, có partial) | 2946 |
| Hoàn toàn sạch (mọi version success/empty) | 19168 |
| Có ít nhất 1 version lỗi/thiếu nguồn | 880 |
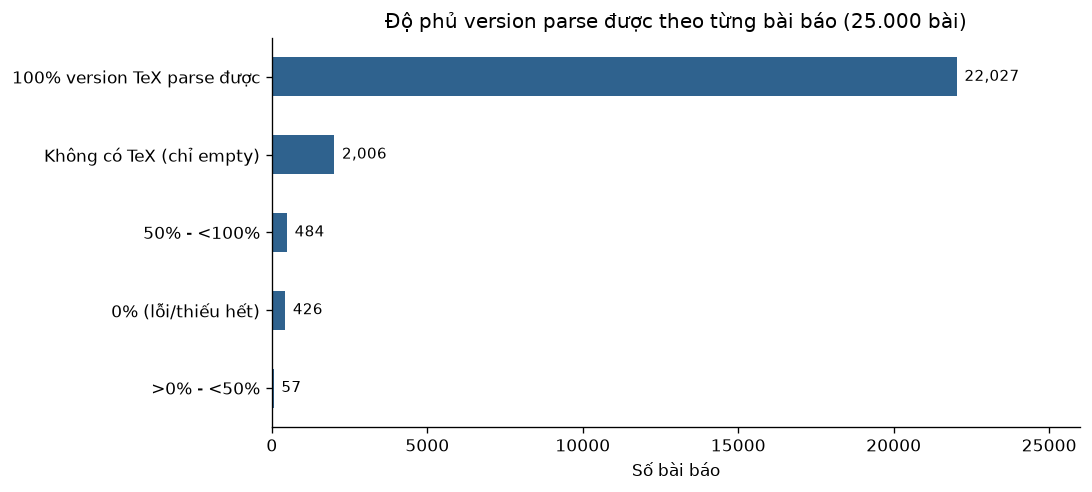
Bảng 6.3. Phân bố tỷ lệ version TeX parse được trên mỗi bài báo (25.000 bài).
| Số bài báo | |
|---|---|
| Không có TeX (chỉ empty) | 2006 |
| 100% version TeX parse được | 22027 |
| 0% (lỗi/thiếu hết) | 426 |
| 50% - <100% | 484 |
| >0% - <50% | 57 |
Tài liệu và mã nguồn tham chiếu#
Mã nguồn triển khai: src/parser/gather.py.
Mã nguồn triển khai: src/parser/latex.py.
Mã nguồn triển khai: src/parser/hierarchy.py.
Mã nguồn triển khai: src/parser/main.py.